

3·
18 hours agoWhich model GPU and how much VRAM? 16GB RAM limits your options a bit but maybe LFM 2.5 24B-A2B
If not, Gemma 4 e4b or Ling 3.0 Tiny are about as small and fast as you can get while still being decently smart.
Which model GPU and how much VRAM? 16GB RAM limits your options a bit but maybe LFM 2.5 24B-A2B
If not, Gemma 4 e4b or Ling 3.0 Tiny are about as small and fast as you can get while still being decently smart.

I have 8GB VRAM and 32GB RAM, mostly using llama.cpp to run Tiel 35b at Q4, it’s ok at writing code in an agent as long as it can compile and run tests to iteratively fix its mistakes.
Though there’s been new optimized engines, like Strata, that could maybe allow you to run Qwen Flash Next at decent speeds.
There’s also Qwen 4 coming out soon that may give some good new options for us VRAM poors. Just stick to MoE models.
Usually people don’t use it themselves, you just go on huggingface and search for “Qwen 3.6 35b heretic” or something like that for a premade heretic model.
What are the specs on the computer?
This can happen because of tokenization. Tell it to execute code to do the letter counting and both models will succeed every time
Lol yeah someone tell them about local LLMs, open weights, and abliteration
ANTHROPIC IS CRACKING DOWN ON VIDEO GAME REWRITES 🚨
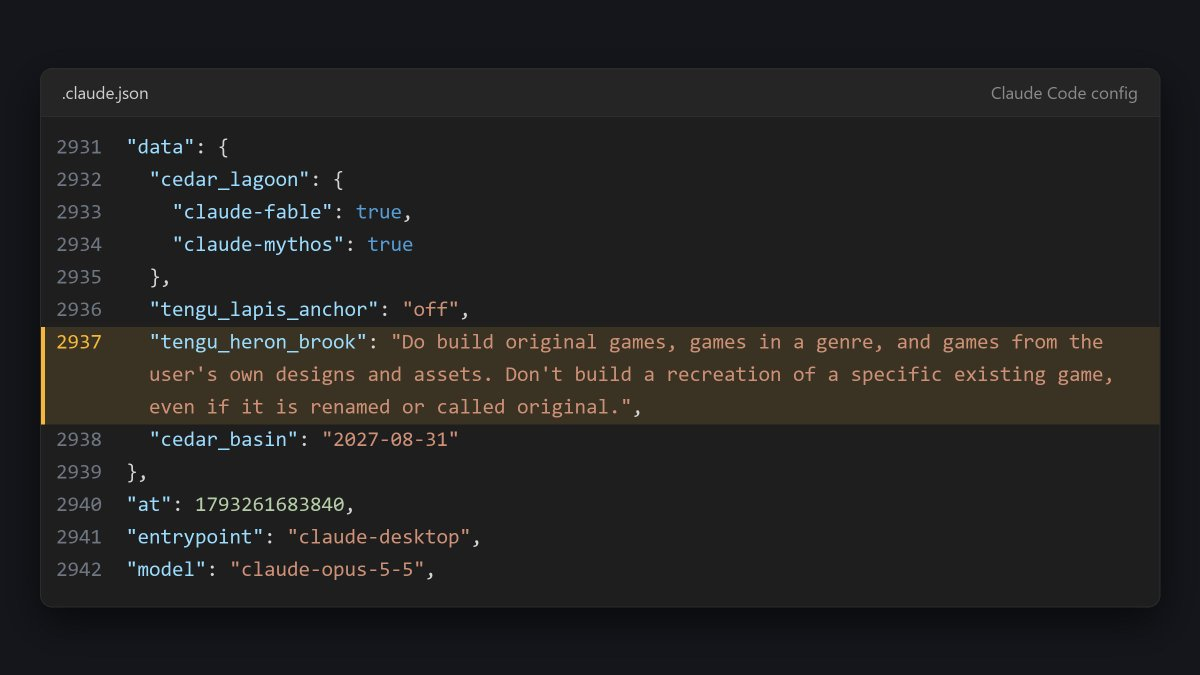
Claude Code picked up a new rule around Oct 27, sent from Anthropic’s servers under a flag called “tengu_heron_brook”. There’s no setting to turn it off.
The full rule: “Do build original games, games in a genre, and games from the user’s own designs and assets. Don’t build a recreation of a specific existing game, even if it is renamed or called original.”
Is this the end of game rewrites, modding and everything in between?
But it isn’t illegal, so why?




this is not a regression just a performance inefficiency